
AI success is often discussed in terms of models, prompts, and applications, but the real work begins earlier. Before an AI system can produce useful output, teams need dependable data workflows that move information from scattered sources into a form that can be trusted, tested, and used. Without that foundation, even advanced AI tools can produce inconsistent results, miss important context, or create avoidable risk.
A strong AI data workflow is more than a technical convenience. It gives data teams, developers, cloud engineers, and business leaders a shared process for deciding what data is usable, how it should be prepared, who owns it, and how quality will be measured over time. That matters because AI systems do not operate in isolation. They depend on operational systems, customer records, application logs, documents, analytics platforms, and cloud environments that are constantly changing.
The Work Before the Model
Many AI issues are easier to prevent in the data workflow than to correct after deployment. Teams need to know where data comes from, how it has changed, and whether it represents the task the model is expected to perform. A model trained on poorly defined or poorly maintained data may appear effective in a test environment, then struggle when exposed to real users, new inputs, or shifting business conditions.
This is where data engineering becomes central to generative AI readiness. Data engineers build the systems that collect, move, clean, join, and store data. They also help create repeatable processes, so teams are not manually rebuilding datasets for every project. For AI teams, that repeatability is critical. It supports better experimentation, clearer evaluation, and faster troubleshooting when outputs do not meet expectations.
Governance also plays a practical role. Clear rules for access, lineage, documentation, and version control help teams understand which data was used, when it was updated, and whether it is appropriate for the use case. These practices are especially important when AI is used in workflows that affect customers, employees, operations, or decision-making.
Building Skills for AI-Ready Teams
AI data pipelines require a mix of skills. Python helps teams automate preparation and analysis. SQL remains essential for querying structured data and validating source systems. Cloud platforms support scalable storage and processing. Visualization helps teams spot outliers, gaps, and patterns before they become model issues. Machine learning knowledge helps technical teams understand how data choices affect model behavior.
The most effective teams do not treat these skills as separate specialties. They build fluency across data science, engineering, analytics, cloud, and AI/ML so people can collaborate across the full project lifecycle. That shared understanding helps teams ask better questions early, reduce rework, and connect technical decisions to business outcomes.
AI initiatives move faster when teams have a reliable data foundation and the skills to manage it. Strong pipelines make AI work more transparent, more testable, and easier to improve after launch.
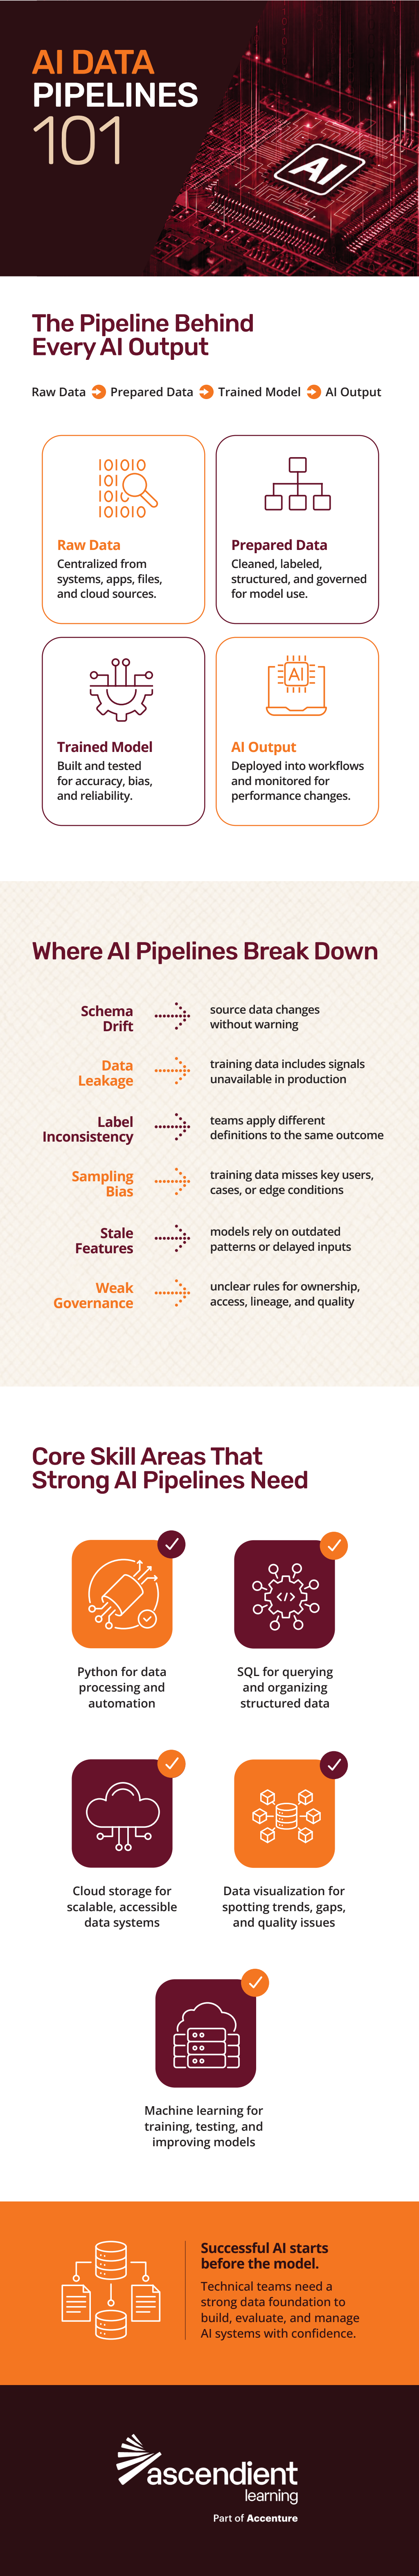
For a quick visual guide to how data moves from raw inputs to AI outputs, explore the accompanying infographic.